
HydraDB: Building Memory That Evolves
Last time I wrote about memory, I shipped a minimal Mem0-style system — vectors, LLM-as-judge, ADD/UPDATE/DELETE on extracted facts. It worked. People liked it. But the deeper I went, the more I reali

Well, let’s discuss the origin of normal-memory going into the bushes. I was in on a call with a bunch of builder friends a couple of months back, all of us discussing AI tools and agents and memory. This was right around the time SuperMemory founder...

If you’ve ever wondered how AI chatbots like me (hi, I’m Grok from xAI!) get so clever, you’re in for a treat. Today, we’re diving into two game-changing methods: Context-Augmented Generation (CAG) and Retrieval-Augmented Generation (RAG). These are ...
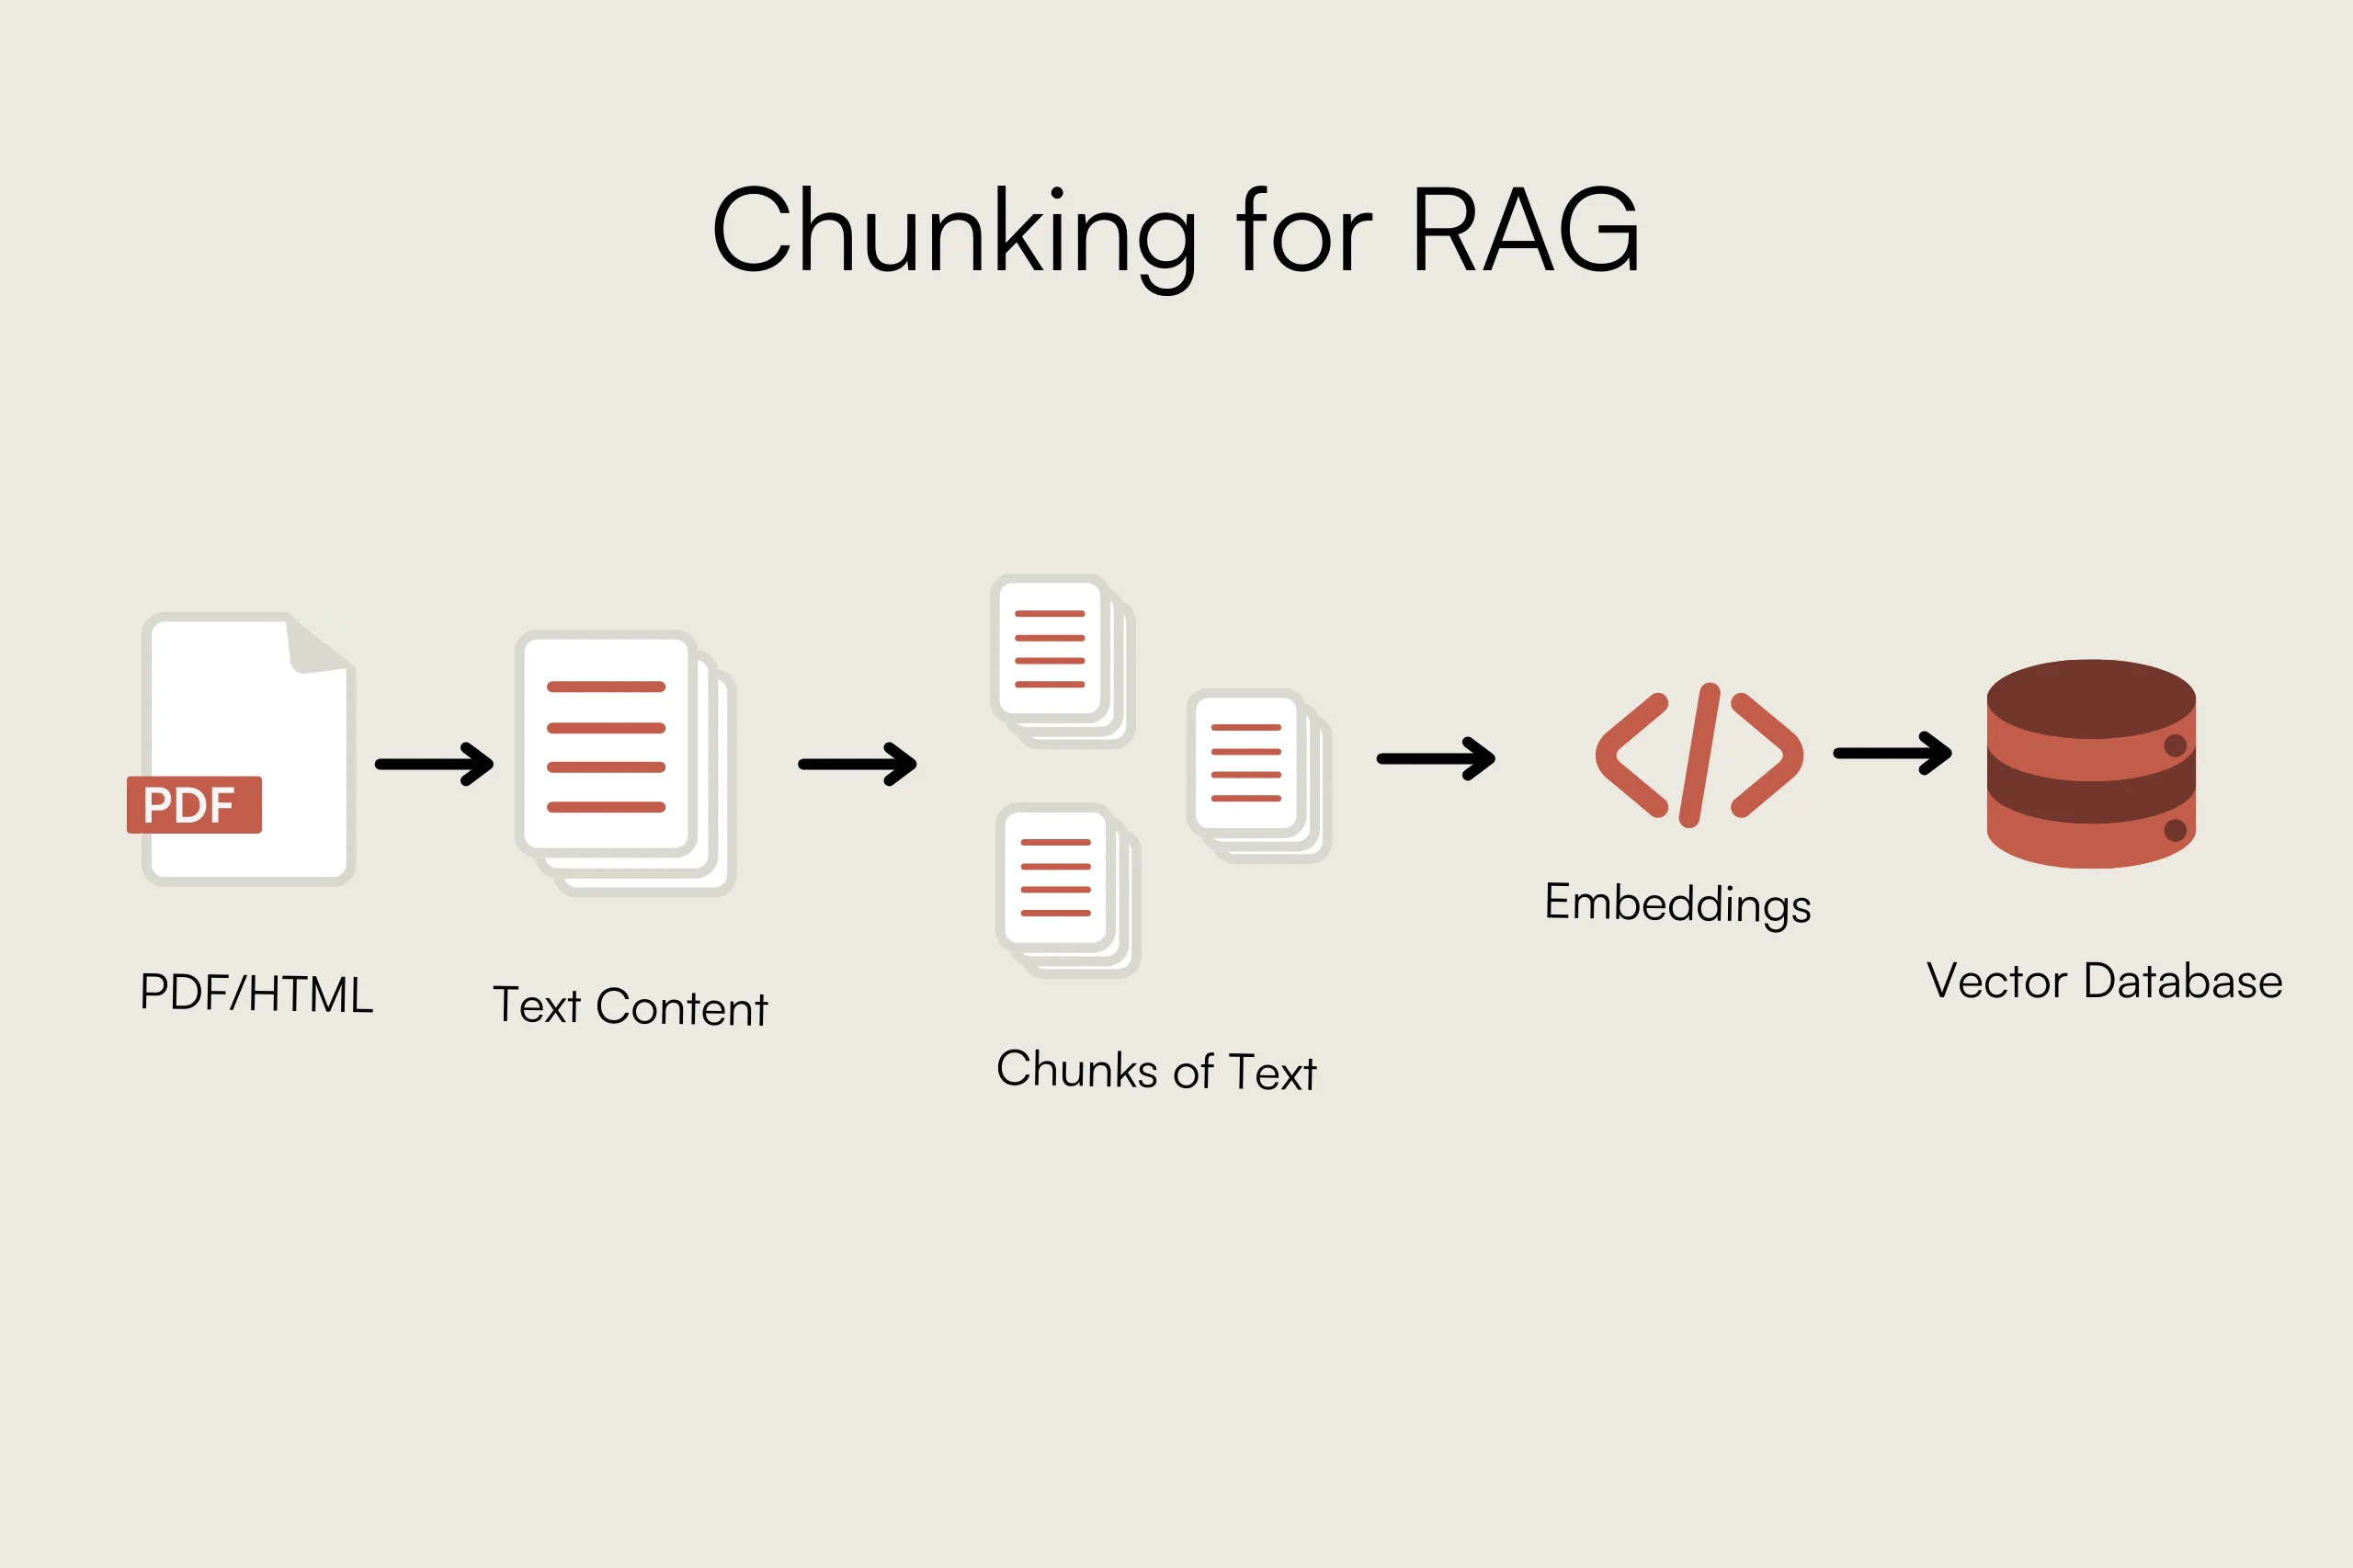
Introduction to Data Processing Techniques If you've ever worked with large structured datasets, you know the struggle of indexing them efficiently while still retrieving meaningful, context-aware results. When it comes to unstructured data, like PDF...
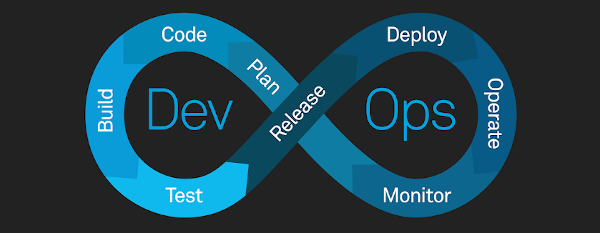
This blog aims to guide you through the creation of your inaugural CI/CD pipeline using Jenkins, seamlessly integrated with three AWS instances and fortified with indispensable tools such as SonarQube and Docker. This comprehensive guide will equip y...
In this blog, we delve into the core of creating a basic chat application, focusing intently on the foundational aspect: setting up the server for peer-to-peer communication. Join this journey as we decipher the underlying mechanics that power this d...
In this blog, we will dive into the world of Docker and explore its basics, shedding light on its fundamental concepts, advantages, and use cases. Whether you are a developer, system administrator, or IT professional, this beginner's guide aims to eq...


